Why “AI readiness” matters before you automate anything
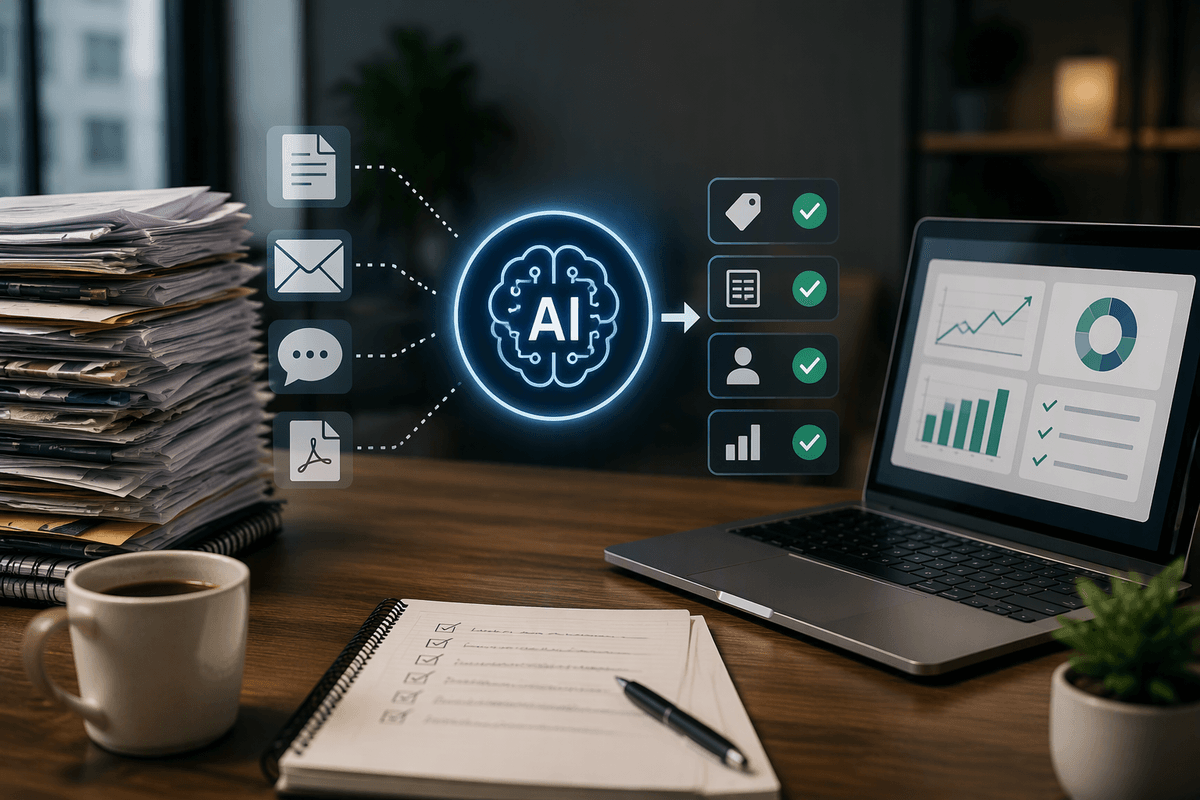
A familiar pattern: a team buys an automation tool, runs a pilot, and then stalls because the “easy” part was the software. AI readiness is the work you do before that purchase becomes a sunk cost—confirming you have usable data, stable processes, clear decision rights, and managers who can absorb change without breaking service levels. Without that groundwork, automation tends to amplify existing inconsistencies: mismatched definitions, undocumented exceptions, unclear approvals, and shadow spreadsheets.
Readiness also sets expectations for risk and effort. Even successful automations carry costs—cleaning data, mapping workflows, training supervisors, redesigning roles, and documenting controls for HR, legal, and audit. Treat readiness as a baseline check: if you can’t describe how work gets done today, you won’t be able to measure whether AI is improving it tomorrow.
Spot the automation opportunities that actually pay off
A common temptation is to start with the flashiest use case—chatbots, auto-summarization, “agentic” workflows—because it demos well. The opportunities that pay off in real operations usually look quieter: high-volume tasks with clear inputs and outputs, repetitive decisions with stable rules, and handoffs that currently depend on copying data between systems. Think invoice matching, employee onboarding checklists, benefits eligibility triage, contract metadata capture, or ticket routing where categories are already defined. These are easier to test, easier to measure, and less likely to create surprise policy issues.
Pressure-test candidates with three questions: can you define “good” output in a sentence, can you measure time/cost/error today, and what happens when it’s wrong. If the downside is regulatory, payroll-related, or customer-impacting, budget for human review and exception handling. That adds cost, but it’s often the difference between a pilot that proves value and one that quietly gets turned off.
Check your data reality: quality, access, and permissions
You can usually tell your data reality by watching what people do when they need an answer fast: they export to CSV, reconcile two reports, and keep a “master” spreadsheet because no system is trusted end-to-end. Automation will inherit those gaps. Start with a short inventory of the few fields your first use cases depend on (vendor ID, job code, start date, ticket category), then test them the way operations experiences them: completeness, freshness, duplication, and whether the same term means the same thing across systems.
Access and permissions are the second failure point. Many pilots stall because the team can’t legally or technically pull data from HRIS, finance, or email, or because least-privilege rules block the service account that runs the workflow. Decide who is allowed to use which datasets for which purpose, and document it. Expect trade-offs: tighter permissions reduce risk but slow delivery, and cleaning data takes time away from day-to-day work.
People and roles: what changes for employees and managers
When automation enters a workflow, the first visible change is usually not headcount—it’s where judgment sits. Work shifts from “doing” to “checking”: validating inputs, reviewing AI outputs, handling edge cases, and deciding when to override. That means roles need clearer boundaries. If two coordinators currently solve problems by improvising in Slack, an automated flow will force those decisions into explicit rules, queues, and escalation paths. Employees need time to learn the new tools, but they also need a safe way to report failure modes without being labeled “resistant.”
Managers carry the heavier lift. They have to keep service levels steady while redesigning assignments, rewriting SOPs, and defining quality targets that are measurable (error types, turnaround time, rework rate). Budget for practical costs: training time, temporary dual-running of old and new processes, and a named owner for exception handling. Without those commitments, automation becomes “extra work” layered onto existing jobs, and adoption stalls.
Process discipline: standardize before you automate the mess
Watch what happens when someone new joins the team and tries to follow the “process.” If success depends on asking the right person, finding the latest template, or knowing which exceptions are “normal,” you don’t have a process yet—you have a collection of workarounds. Automating that will usually make outcomes less consistent, not more, because the tool will execute the version you encoded, not the version people improvise when reality deviates.
Start by standardizing the minimum that matters: one definition of “done,” one intake path, one place where the work is tracked, and a short list of allowed exceptions with clear escalation. Remove steps that exist only to compensate for missing information, then add checks where errors are actually created (handoffs, approvals, re-keying). This work is slower than building the first bot because it requires agreement across functions, and it can surface uncomfortable gaps in ownership. The payoff is that automation becomes repeatable: you can measure baseline performance, run controlled tests, and expand without rewriting the workflow every time a manager changes.
Risk, compliance, and governance without slowing everything down
Risk shows up when an automated step becomes a “decision” step—approving a payment, changing an employee record, prioritizing a customer complaint—without the controls those decisions normally require. Treat compliance as design input, not a gate at the end: define which actions must have a human approver, what evidence you need for audit (who changed what, when, based on which data), and how you will handle mistakes. For most HR and operations workflows, that means keeping a clear trail of inputs, model outputs, and overrides, plus retention rules that match your existing policies.
Governance stays lightweight when decision rights are clear. Name a product owner for each automated workflow, a data owner for each critical dataset, and a risk reviewer who can set guardrails (access, segregation of duties, acceptable error rates). Avoid committee-driven approvals for every change; use tiered rules instead. Low-risk tweaks ship faster, while payroll, benefits, or regulatory steps require tighter testing and sign-off. The practical cost is time: logging, reviews, and dual-running add effort, but they prevent expensive rework and compliance fire drills.
A practical readiness scorecard and first 90-day plan
Most teams move faster when readiness is a scorecard, not a debate. Rate each dimension 1–5 with a short justification: use-case clarity (measurable baseline and “what if it’s wrong” defined), data fitness (critical fields complete, consistent definitions, refresh cadence known), access/permissions (approved paths, service accounts workable), process stability (one intake, one tracker, documented exceptions), people capacity (named workflow owner, supervisor time for coaching, training plan), and governance (audit trail, human-approval points, tiered change control). Treat any score under 3 as a constraint you must plan around, not “technical debt” to ignore.
Days 1–30: pick one workflow, map it end-to-end, measure current cycle time/error/rework, and inventory the 10–20 fields the automation will touch. Days 31–60: clean the minimum data, standardize the intake and exception paths, and set review thresholds (what requires human check). Days 61–90: run in parallel, track drift and overrides, and lock in ownership for ongoing changes. Expect real costs: dual-running slows teams, and data fixes compete with daily work.
Turning readiness into momentum, not a one-time project
Momentum comes from treating each automation as a product you operate, not a launch you finish. Keep a simple cadence: weekly metrics (cycle time, error, rework, override rate), a short queue of “next exceptions to formalize,” and one owner accountable for changes and outcomes. Build adoption into the job: supervisors need time set aside to coach reviewers and update SOPs, or the workflow quietly drifts back to email and spreadsheets. Budget for maintenance work—access reviews, data definition fixes, vendor updates, and retraining—because the first version will be wrong in predictable ways once volumes and edge cases rise.