Why the AI model market is changing so fast
Most markets don’t change this quickly because the “product” moves slowly. AI models don’t. A single training run can reset the benchmark leaderboard, and a small release—better tool use, a larger context window, cheaper inference—can ripple into pricing, product roadmaps, and buyer expectations within weeks. Distribution also accelerates churn: models ship through APIs, cloud marketplaces, and embedded assistants, so switching is sometimes a config change rather than a procurement cycle.
Teams rarely get the calm period needed to validate quality, reliability, and security across real workloads, and the bill can spike if usage scales before efficiency tuning catches up.
The major players and the roles they’re competing for
You can think of the market as a few overlapping “roles” that companies are trying to own at once: the best general-purpose model, the default enterprise platform, the cheapest high-volume inference engine, and the open ecosystem that sets the baseline everyone must beat.
OpenAI, Google, and Anthropic largely compete for the “default brain” in products and knowledge work, where reliability, tool use, and enterprise controls matter as much as raw benchmark wins. Microsoft and AWS fight to be the procurement-friendly lane that delivers those models with governance, regional hosting, and predictable billing, while also pushing their own offerings. Meta and a long tail of open-weight labs aim to make “good enough” models widely available, pressuring closed providers on price and lock-in. Hardware and model-hosting specialists play a quieter role: if you can’t get capacity, latency, or unit cost under control, the best model on paper becomes hard to ship.
Competition shows up first in pricing, quotas, and bundles
You feel competition first when the invoice changes. Providers adjust per-token rates, add cheaper “mini” tiers, or introduce aggressive promotional credits to pull workloads onto their stack. Quotas and rate limits become the quieter lever: a model might be affordable on paper, but capped throughput can force you into higher tiers or a reserved-capacity deal when you hit production traffic. Even “free” access inside a chat product can shape expectations, then push serious usage toward paid APIs or enterprise plans once teams need logging, admin controls, or higher limits.
Bundling is the second tell. Cloud platforms wrap models with hosting, identity, guardrails, vector search, and monitoring to make the purchase look like a platform decision rather than a model choice. Model vendors bundle tool use, agent frameworks, evaluation dashboards, and fine-tuning pipelines to raise switching costs. The bundles reduce integration work, but they can hide unit economics, complicate attribution, and make it harder to swap models without reworking surrounding services.
Capability races: multimodal, long context, and agent tools
A familiar pattern shows up in product teams: the model is “good enough” in a demo, then it falls apart when you add messy inputs, real documents, and multi-step work. That’s why capability competition clusters around three upgrades buyers can feel immediately. Multimodal models turn screenshots, charts, scans, and short videos into something the same workflow can reason over, reducing the handoff between OCR, vision tools, and text-only prompts. Longer context windows make it practical to load an entire contract set, support thread, or codebase slice at once, shifting effort from retrieval plumbing toward better evaluation and guardrails.
Agent tools are the third race: structured function calling, browser or system connectors, and “run-and-check” loops that let the model take actions and verify results. Long context and tool chains can multiply latency and token spend, and small error rates compound across steps. Teams that measure step-level failure, cap actions, and keep a fallback model often ship faster than teams chasing the biggest spec sheet.
Open versus closed models: control, cost, and lock-in
A common fork appears once a prototype becomes a product: do you keep buying a closed model as a managed service, or adopt open-weight models you can run (or have a host run) with more control? Closed models usually win on “it just works”—strong tooling, steady upgrades, and fewer knobs to manage. The trade is dependency: your prompts, evals, and surrounding services can quietly become tuned to one provider’s quirks, and changes to pricing, rate limits, or model behavior can force unplanned rework.
Open-weight models shift power back to the buyer. You can choose where data runs, tune for your domain, and set your own latency-versus-cost targets. But the bill doesn’t vanish; it moves. You pay in GPU capacity planning, model serving, observability, security patching, and ongoing quality work. Many teams end up hybrid: open models for predictable, high-volume tasks, and a closed “frontier” model for the hardest cases—designed behind an abstraction layer so swapping doesn’t break the product.
Safety, regulation, and trust become competitive features
The recognizable shift in vendor conversations is how quickly “Can it do it?” turns into “Can we defend using it?” Buyers now ask for audit logs, data retention controls, regional processing options, and clear terms on whether prompts or outputs train future models. Safety features—policy filters, jailbreak resistance, and configurable moderation—have become part of the product surface, not an afterthought, because a single incident can create customer churn, legal exposure, or a board-level escalation.
Regulation adds pressure and opportunity. Enterprise deals increasingly hinge on documentation: risk assessments, third-party security reports, incident response processes, and options for higher-assurance deployments. Providers that can package compliance support—without turning implementation into a months-long integration—often win even if their model is slightly behind on benchmarks. The stricter controls can reduce capability or raise cost: tighter filters cause false positives, and private hosting or dedicated capacity can price out smaller teams.
How buyers and builders can choose amid constant churn
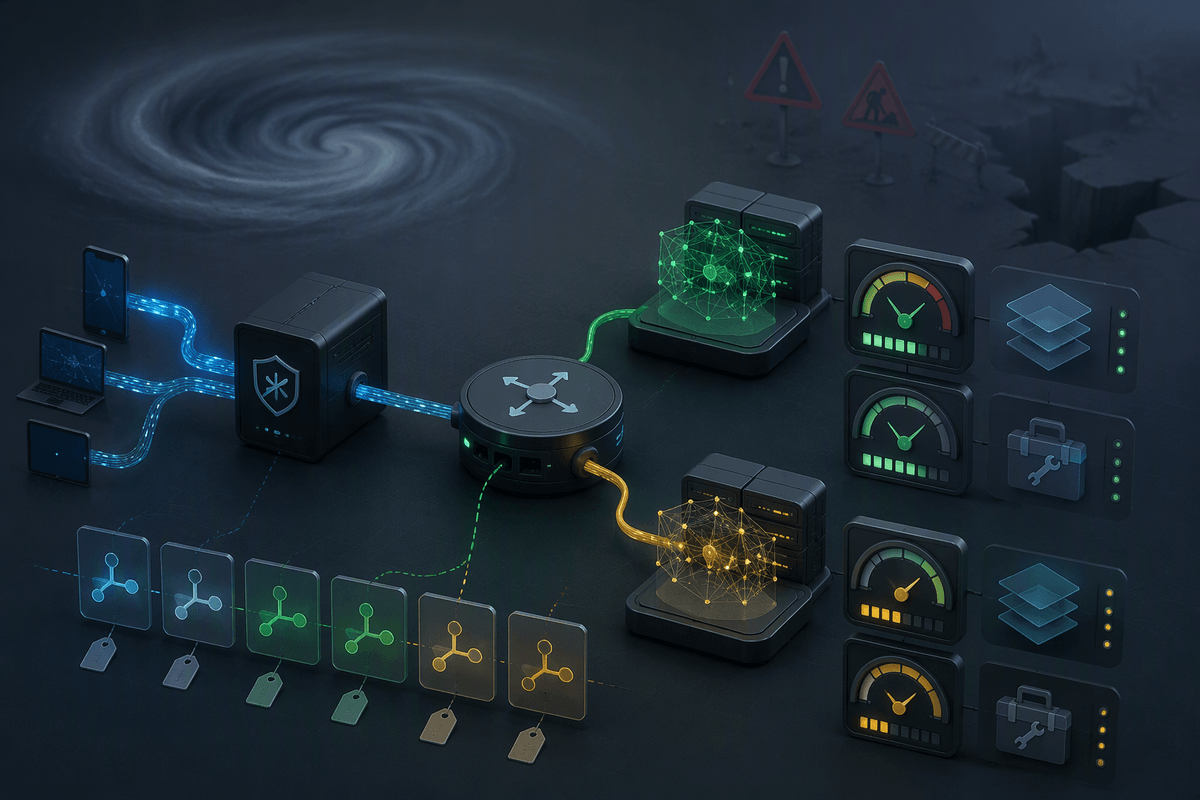
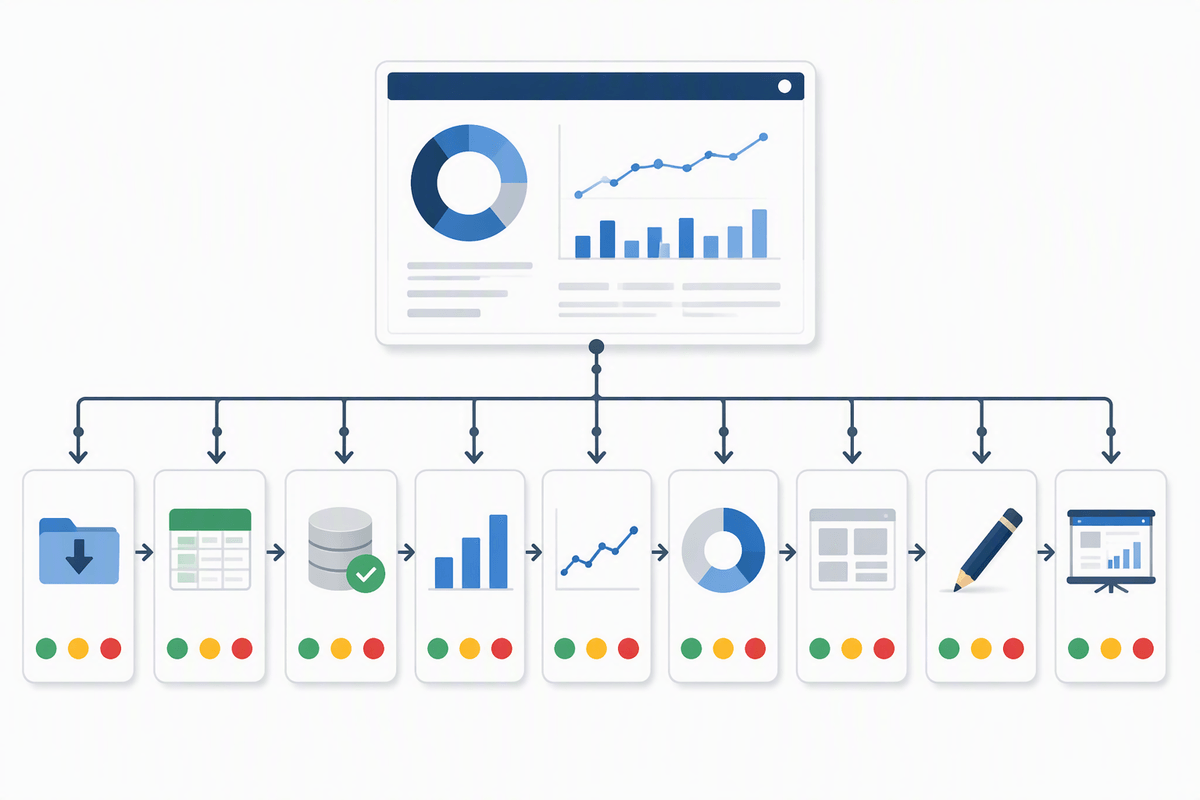
A practical buying pattern is to treat “the model” as a replaceable component and buy the surrounding constraints first. Start by writing down what actually matters in production: target latency, peak throughput, acceptable error rate, data residency, retention, and logging. Then pick two candidates—a primary model and a fallback—and force both through the same evaluation harness using your real prompts, documents, and edge cases. Many teams only test average quality; the more revealing test is tail behavior: hallucinations under stress, refusal patterns, tool-call mistakes, and how often a response needs human review.
Procurement choices can reduce future churn more than any benchmark. Prefer contracts that separate model usage from platform bundles when possible, and negotiate for predictable rate limits, clear deprecation timelines, and the right to export logs, traces, and evaluation artifacts. Watch for hidden coupling in agent tools, safety policies, and proprietary retrieval layers; these are where “switching is a config change” stops being true.
Builders can buy flexibility with a small amount of upfront engineering: a model router behind a stable interface, prompt/version control, and spend guards that cap context and tool depth. The cost is real—extra integration work and ongoing eval maintenance—but it’s usually cheaper than a forced migration under a surprise price change or model behavior shift.
What this competition likely means over the next year
The familiar budget pattern will keep repeating: headline prices drift down, but total spend stays volatile because longer context, multimodal inputs, and multi-step agents quietly multiply tokens and tool calls. Expect more “good enough” open-weight options to squeeze routine workloads, while closed frontier models compete by packaging reliability—better eval tooling, stronger uptime commitments, and enterprise-friendly controls—into higher-priced tiers.
Switching costs will move from models to glue. The teams that fare best will treat prompts, retrieval, tool schemas, and safety policies as portable assets, and will keep a second provider warm. The practical constraint is ongoing evaluation work; without it, even small vendor changes become production incidents.