Why turning language into data is harder than it sounds
You’ve probably seen a dashboard that claims it can read customer feedback, tag complaints, and summarize what people want. The surprise is how quickly “simple text” turns into edge cases. People misspell words, switch languages mid-sentence, use sarcasm (“love waiting on hold”), and reference context you don’t have (“that issue is back”). Even basic questions like what counts as the same topic—“refund,” “chargeback,” “billing error”—depend on business rules, not just vocabulary.
To make language usable, you have to force messy, flexible expressions into consistent labels, numbers, or fields a system can count and act on. That means deciding what you care about (sentiment, intent, entities, urgency), handling ambiguity, and accepting trade-offs: stricter rules miss nuance, broader rules create false positives. The practical difficulty is that each extra bit of reliability usually costs time—collecting examples, cleaning data, reviewing outputs, and updating definitions as your products and customers change.
What “machine-readable” looks like in real NLP outputs
Open a pile of support tickets and ask, “What can a system actually do with this?” The answer is rarely “understand it” in a human sense. It’s to produce structured outputs that other software can store, filter, and trigger actions from. That might look like a category label (“Shipping delay”), a sentiment score (0.2 negative to 0.9 positive), or a short list of extracted fields such as {order_id: 84721, product: “Model X”, issue: “won’t turn on”}. For search, the output may be a set of keywords or a numeric vector that helps match similar questions, even if the wording differs.
These outputs are useful because they’re consistent, but they’re not free of judgment. A model can assign “Billing” vs. “Account” with 70% confidence, and you still have to decide what happens below 80%—auto-route, ask a follow-up, or send to review. The “machine-readable” part is the shape and stability of the data, not perfect certainty.
From raw text to clean input: the hidden preparation work
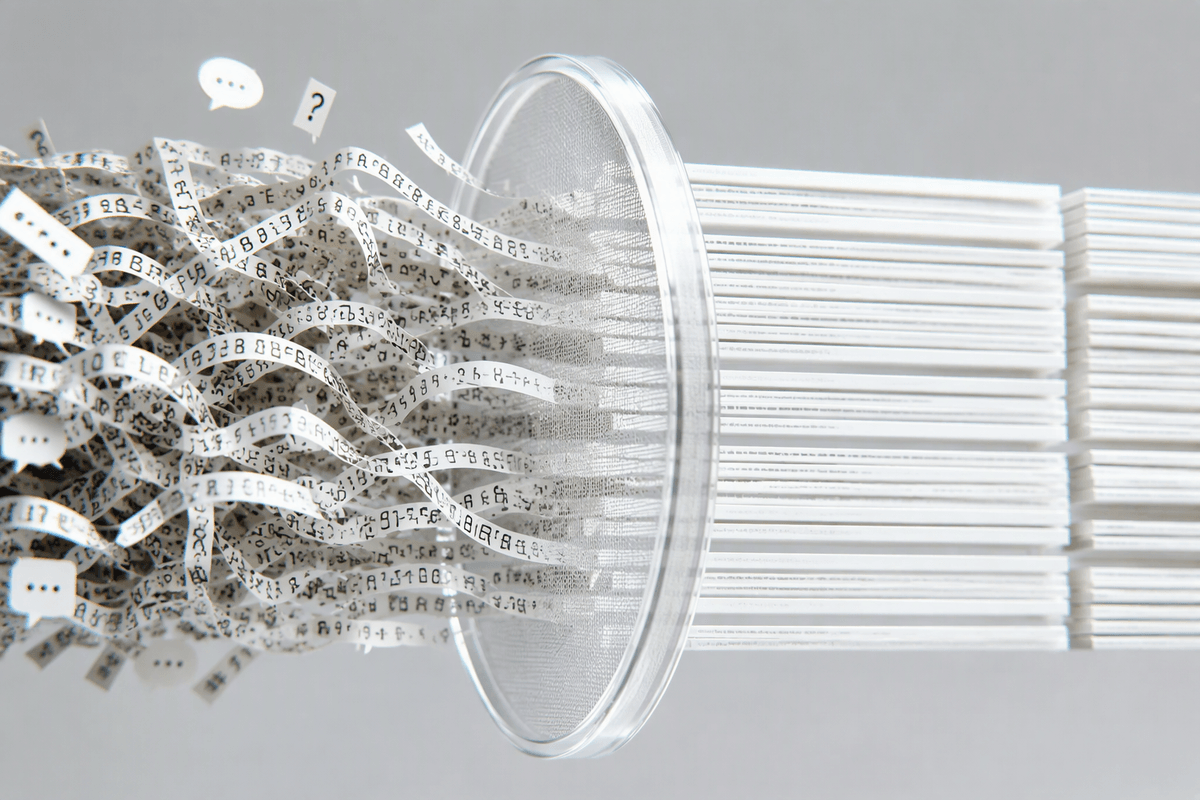
Look at a real inbox export and the first problem is rarely “the model.” It’s that the text isn’t in a stable form yet. Emails contain quoted threads, signatures, boilerplate disclaimers, and pasted error logs. Chat transcripts mix system messages with customer messages. Tickets may bundle multiple issues into one paragraph, or split one issue across ten short updates. Before you can classify or extract anything reliably, you usually need to strip obvious noise, separate fields (subject vs. body, agent vs. customer), and normalize basics like casing, punctuation, and weird characters.
Then comes the less visible work: deciding what counts as a “document,” how to handle duplicates, and what to do with short, context-free messages like “same here.” You may standardize dates, product names, and IDs, detect language, and choose whether to keep emojis or formatting that carry meaning. Every cleaning rule can delete useful signal, and reviewing edge cases takes real time from people who already have a day job.
Two main paths: rules and models (and when to mix)
If you need a system to spot order numbers, detect “unsubscribe,” or route messages that contain a known product code, hand-built rules are often the fastest path. You write patterns and dictionaries, test them against real examples, and adjust as new phrasing shows up. Rules are predictable and easy to justify to stakeholders, but they get brittle when wording varies (“can’t log in” vs. “locked out”), and maintenance becomes a steady cost as products, policies, and slang evolve.
Models take the opposite approach: they learn from labeled examples (or large pretraining) to generalize across phrasing. That makes them better for fuzzy categories like intent, topic, or tone, but they introduce new constraints—needing enough representative data, dealing with shifting performance when customer language changes, and handling cases where confidence is low. In practice, teams mix both: rules for high-precision “must-catch” items and data validation, models for the flexible parts, and a review queue for the uncertain middle.
How modern models represent meaning: vectors, context, and embeddings
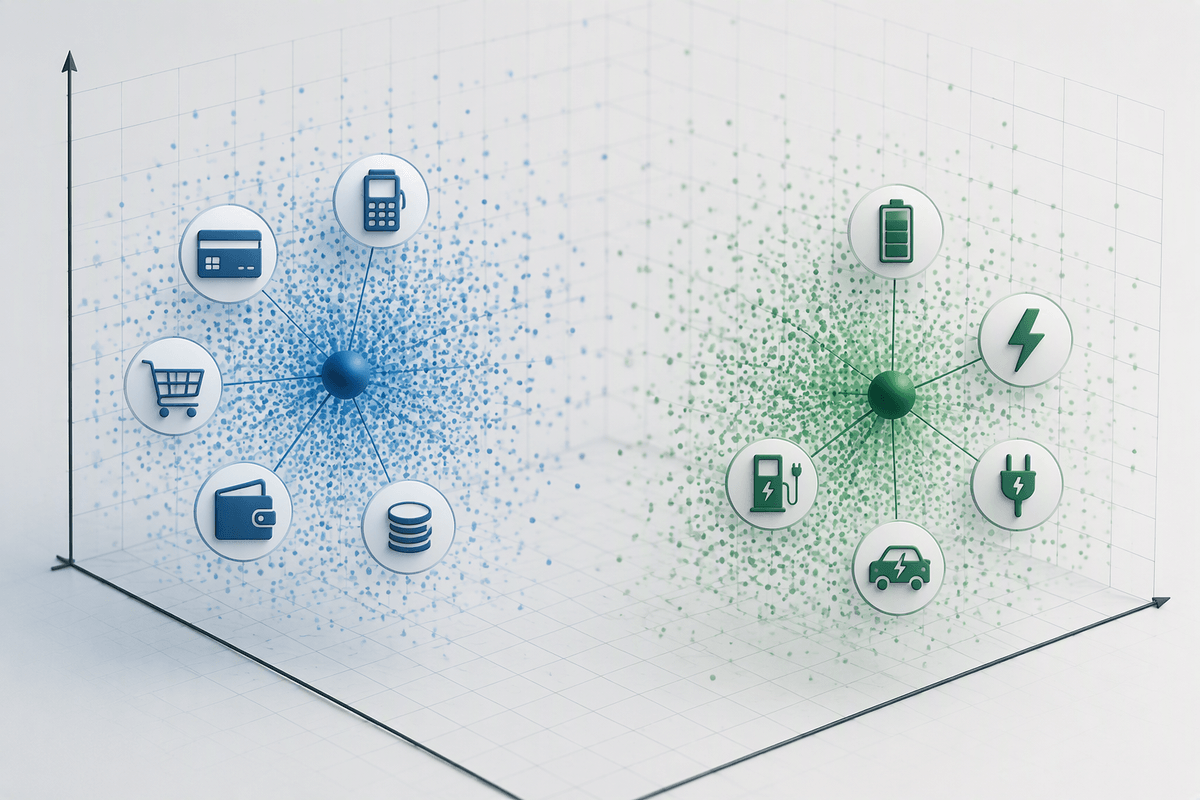
Picture two tickets: “My package never arrived” and “Still waiting on delivery.” A rules list might miss the match unless it includes both phrases. Modern models get around this by turning text into numbers—vectors—that place similar meanings near each other, even when the words differ. These numeric representations are often called embeddings. Instead of asking “does it contain the word delivery,” you can ask “is this close to other shipping-delay examples,” which is why embeddings show up in search, clustering, and routing.
The catch is that meaning changes with context, and newer models try to capture that by creating different vectors for the same word in different sentences (“charge” on a credit card vs. “charge” a battery). That helps with ambiguity, but it adds practical constraints: you need consistent examples from your own domain, you may have to re-embed content when products or policies change, and similarity scores still need thresholds and human review for the messy borderline cases.
Measuring success: accuracy isn’t enough for language tasks
Imagine a classifier that’s “90% accurate” at tagging tickets, yet agents still complain it’s useless. That can happen when the 10% includes the most expensive failures: routing cancellations to sales, missing fraud signals, or misreading “great, another outage” as positive. Language work is usually imbalanced—most tickets are “how-to,” few are “security”—so raw accuracy can look great while the system ignores the rare cases you care about. Measures like precision and recall force the right question: when the system flags something, how often is it correct, and how much does it miss?
Success also depends on what you do with uncertainty. A model that only auto-routes when it’s confident and sends the rest to review may reduce handle time more than a “higher accuracy” model that guesses on everything. Calibration (whether a 0.8 score really behaves like 80% correct), category-level breakdowns, and manual spot checks matter because business language shifts. The practical cost is ongoing evaluation: sampling, labeling, and revisiting definitions when teams change what “billing issue” is supposed to mean.
Choosing a first NLP project that actually delivers value
A good first NLP project is one where “good enough” creates immediate leverage. Start with a high-volume, low-risk workflow: auto-tagging tickets into a short set of stable categories, extracting order IDs, or powering better internal search over past resolutions. Pick an outcome you can measure in days, not quarters—fewer manual clicks, faster routing, shorter time-to-answer—and bake in a fallback for low confidence (review queue, “unsure” label, or simple rules).
Avoid launching with open-ended chatbots or nuanced sentiment promises unless you can fund iteration. You’ll need labeled examples, time from subject-matter reviewers, and a plan for drift as products and policies change. If you can’t name the owner of ongoing evaluation, the project will degrade quietly even if the first demo looks great.