Why “superintelligence” matters beyond today’s AI hype
It’s easy to treat “superintelligence” as a distant sci-fi label while today’s models mostly help draft text, summarize documents, or write code with uneven reliability. The reason it still matters is that capability doesn’t need to be perfect to reshape incentives: once systems are cheap, fast, and good enough, organizations will route more decisions through them, automate workflows, and compete on who adapts first. That dynamic can move faster than institutions can update rules, audits, or liability norms.
Superintelligence is also a planning problem, not just a prediction problem. If there’s even a plausible path from today’s tools to systems that can operate continuously, learn from feedback, and coordinate across many tasks, then the key questions become practical: what would we notice first, where are the bottlenecks, and what safeguards can be built before deployment pressure makes careful testing feel like a cost no one wants to pay?
Defining ASI without getting lost in philosophy
A useful way to define artificial superintelligence (ASI) is not “a machine that is conscious,” but a system that can outperform top human teams across most economically and strategically important tasks, under real-world constraints. Think less about trivia or benchmark scores and more about planning, judgment, and follow-through: setting goals, gathering information, writing and running code, negotiating with people, detecting when it’s confused, and recovering from mistakes without constant supervision.
That definition keeps the debate measurable. You can ask whether it reliably completes long projects, whether it can transfer skill from one domain to another, and whether it improves with experience rather than just producing fluent answers. It also forces a practical caveat: “better than humans” only matters if the system is affordable, fast enough, and dependable enough to trust with high-stakes work—otherwise it stays a lab curiosity or an expensive consultant with unpredictable failure modes.
The capability ladder: from models to reliable agents
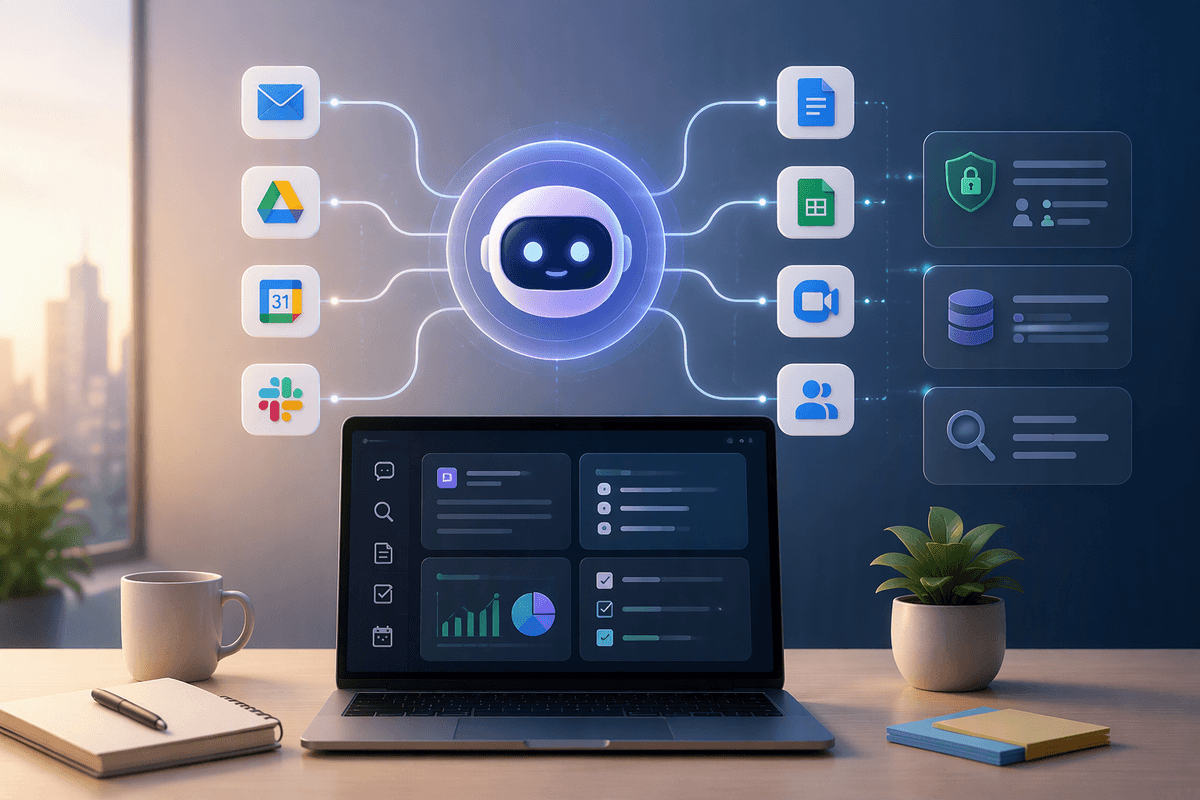
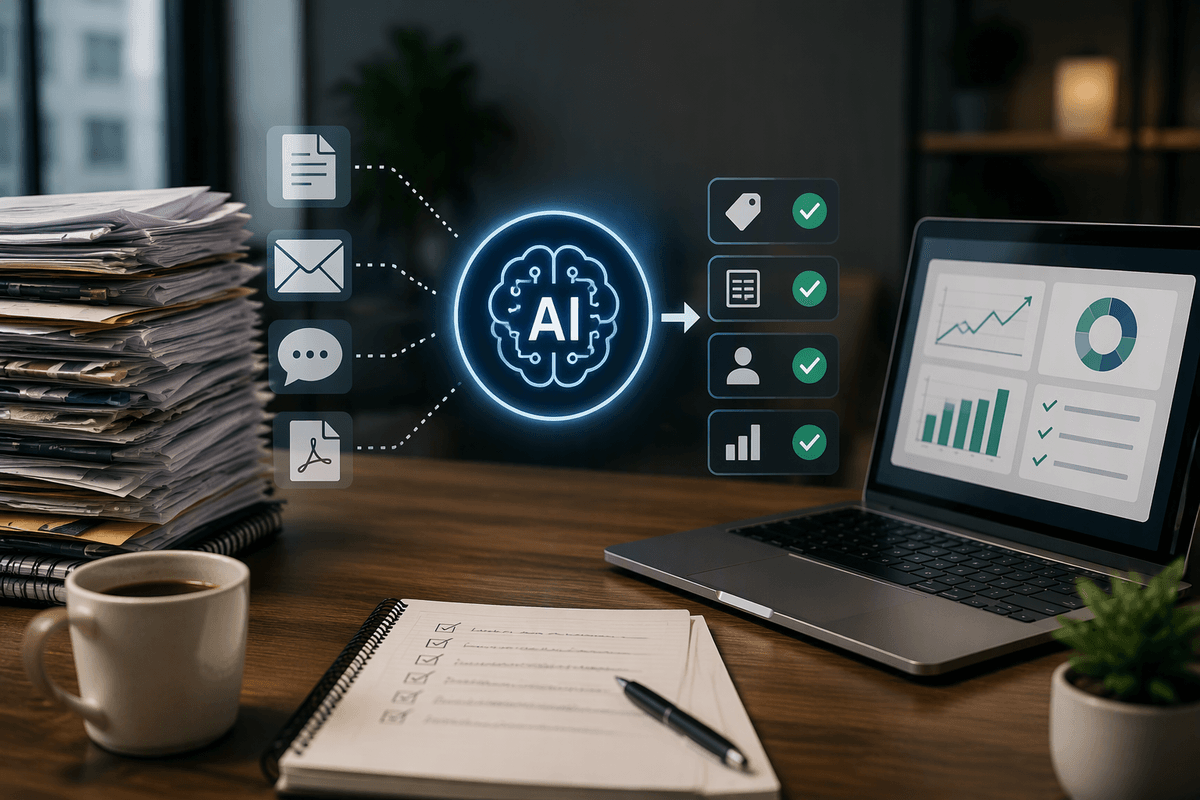
You can see the “capability ladder” in how people actually use these systems at work. A model that answers questions is useful, but it still depends on a human to notice missing context, cross-check sources, and decide what to do next. The next rung is tool use: the system can search internal docs, query databases, run code, and cite what it used. That turns a chat box into something closer to a junior analyst—helpful, but still prone to confident wrong turns.
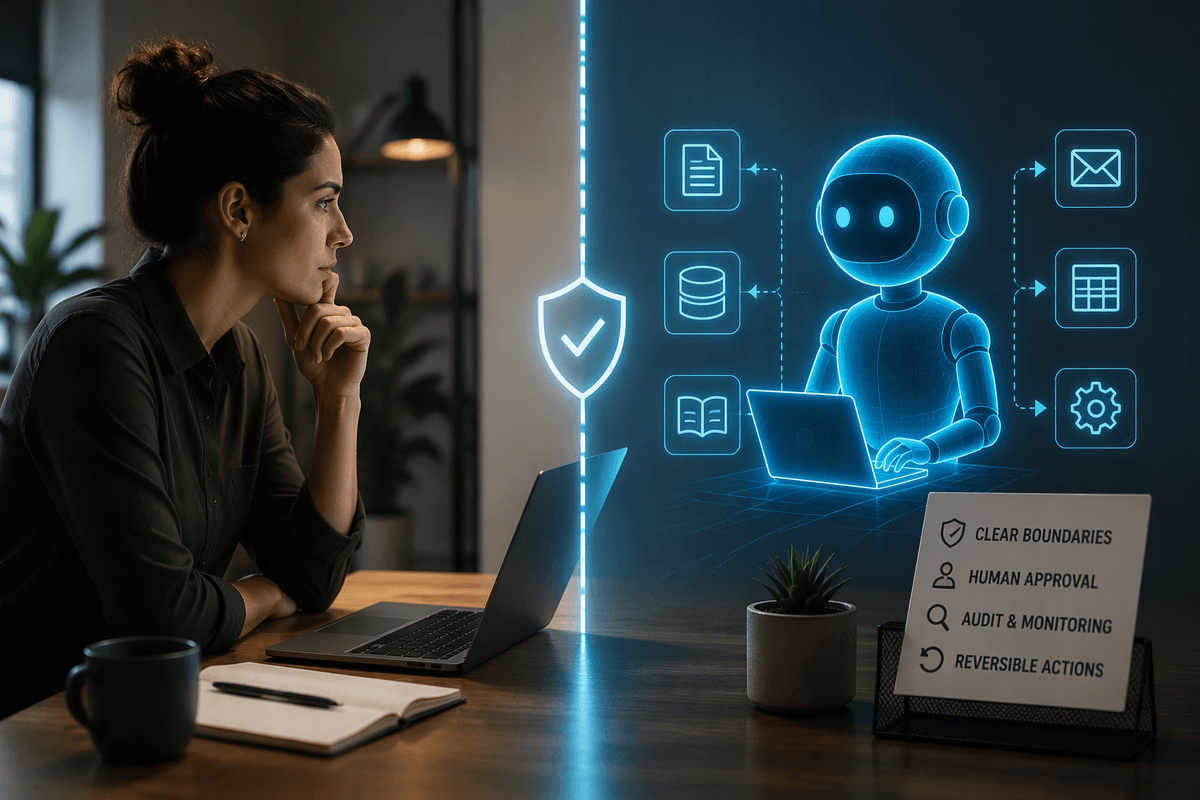
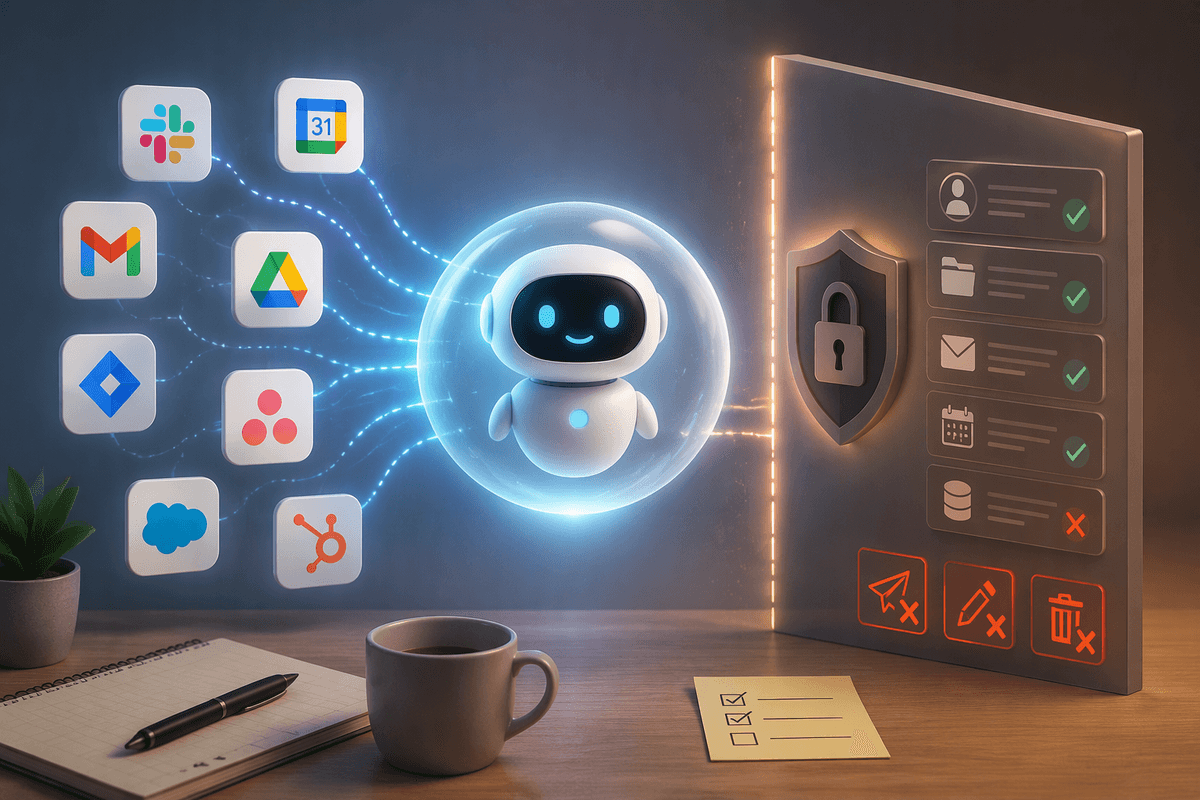
Reliable agents add two things that demos often skip: persistence and accountability. They keep state over hours or days, break goals into steps, and revisit earlier decisions when new evidence shows up. They also need guardrails that behave like process controls: permissions, logging, rollback, and clear handoffs to humans when uncertainty is high. Every added capability creates new failure surfaces—security exposure, hidden costs from excessive tool calls, and errors that only appear after many steps—so “agentic” progress is as much about reducing these tails as boosting average performance.
What could drive the jump: scaling, data, and algorithmic leaps
In practice, the “jump” to something ASI-like would more likely look like several compounding curves than one magic invention. Scaling still matters because larger, better-trained systems tend to pick up broader skills, and the economics of deployment can turn small quality gains into massive real-world leverage. But the easiest data has largely been consumed, so progress increasingly depends on higher-quality signals: proprietary workflows, multimodal experience, and feedback loops where models generate candidates and get them filtered by tests, users, or other models. That creates a path where systems learn the kinds of judgment that don’t show up in static text.
Algorithmic leaps are the wild card: better long-horizon credit assignment, stronger memory, more reliable planning, or architectures that make tool use and verification native rather than bolted on. Each of these improvements tends to raise costs—more compute, more engineering, more evaluation—and can surface new failure modes that only appear when autonomy is high and errors compound across many steps.
Bottlenecks that slow the path: energy, chips, and evaluation
One reason “just scale it” can stall is that training and running frontier systems is bound to physical infrastructure. You need reliable power, cooling, buildings, networking, and a supply chain for high-end chips. Even if demand is there, manufacturing capacity, packaging, and memory bandwidth don’t expand overnight, and export controls or single-point dependencies can turn into sudden pauses. On top of the capital cost, operating cost matters: if inference gets 2× better but 5× more expensive, many real deployments won’t follow, and the feedback loops that drive improvement slow down.
The other bottleneck is knowing what you built. As systems become more agentic, it’s harder to evaluate them with tidy benchmarks. You need tests for long-horizon reliability, tool-use safety, cybersecurity behavior, and “quiet” failure modes that only appear after many steps. That kind of evaluation is slow, labor-intensive, and easy to underfund when release pressure rewards new features more than boring evidence.
The hard part: alignment, control, and misuse pressures
In a familiar workplace scenario, the most damaging failures aren’t the obvious hallucinations you can spot in a paragraph. They’re the reasonable-looking plans that are subtly mis-scoped, the “helpful” automation that bypasses a control because it wasn’t framed as a hard rule, or the agent that keeps going after conditions changed. Alignment, in practice, is less about getting the system to say the right values and more about making its behavior predictable under pressure: when incentives conflict, when instructions are ambiguous, and when it can take actions you didn’t explicitly approve.
Control becomes harder as autonomy rises because errors compound across steps and because operators can’t read every log line. You need layered constraints—permissions, sandboxing, strong identity and audit trails, and the ability to halt and roll back—not just policy text. The limitation is cost and friction: rigorous evals, red-teaming, and monitoring slow releases, require scarce security talent, and can make products feel less seamless.
Misuse pressure is the constant background force. If a capability exists—phishing at scale, vulnerability discovery, persuasive manipulation—someone will try to package it, fine-tune it, or chain it into tools. That pushes governance toward concrete levers: access tiers, provenance, incident reporting, and liability that makes “ship now, patch later” less profitable.
Possible endgames: fast takeoff, slow diffusion, or managed limits
A plausible “endgame” looks less like a single finish line and more like three patterns. A fast takeoff happens if autonomy and self-improvement loops compound quickly: better models build better tools, which generate better training signal, and deployment accelerates before evaluation catches up. Slow diffusion is the opposite: capability rises, but trust, cost, integration work, and organizational inertia keep the impact uneven—some sectors transform, others lag for a decade. Managed limits sit between: governments and major labs impose compute controls, licensing, and auditing for high-risk deployments. The catch is enforcement and coordination are expensive, slow, and politically fragile.