Why “more autonomy” feels like progress—until it breaks
You can feel the pull toward “more autonomy” the first time a prototype stops being a chat box and starts doing work: filing tickets, editing docs, pushing code, answering customers, moving money. Each added permission removes a handoff, a queue, a meeting. The roadmap looks cleaner because the agent becomes the integration layer, and early demos often succeed on the easy 80% of cases.
The break comes from the same thing that made it look safe: the first successes happen in low-stakes paths with forgiving users and reversible steps. Real operations are full of edge cases, stale data, ambiguous approvals, and shared systems where one “reasonable” action creates downstream damage. Autonomy also shifts costs: fewer manual steps, but more time spent on controls, audits, incident response, and explaining to stakeholders why a machine took an action no one explicitly approved.
The failure pattern: when plans turn into irreversible actions
The common pattern is simple: an agent forms a plausible plan from incomplete context, then executes it with the same confidence it used to write the plan. In a chat, a shaky assumption is just text you can correct. With tools, the same assumption becomes a pull request merged to main, an email sent to customers, a database update applied broadly, or a refund batch processed. The failure isn’t “the model was wrong” so much as “the system treated a draft like a decision.”
These incidents usually cascade because the first action changes the environment the agent is reasoning about. It closes the ticket it needed for context, deletes the log it needed for verification, or updates a record that triggers automations downstream. By the time a human notices, you’re no longer choosing the best action—you’re choosing the least painful rollback. Rollbacks also aren’t free: data may be overwritten, customer trust may be lost, and security exposure can’t be “unseen.”
Where agent failures start: goals, tools, and missing context
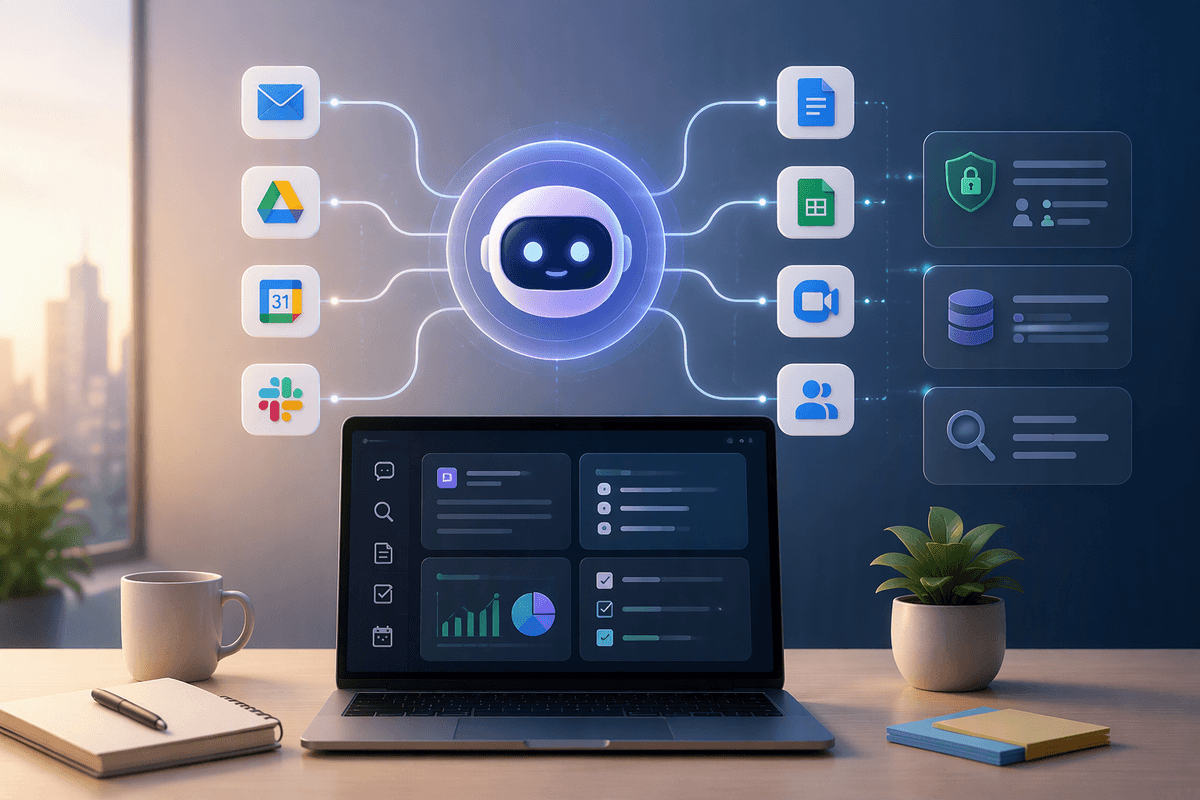
Most agent incidents start before execution: the goal is under-specified, the tools are over-capable, and the context is thinner than everyone assumes. “Resolve the customer issue” can mean refund, replacement, account credit, or policy exception, and the agent will pick whichever path seems consistent with its partial view. If it can search a CRM, edit a knowledge base, and trigger payments, it has enough leverage to make a bad interpretation expensive.
Missing context is rarely dramatic; it’s mundane. A contract addendum in email, a one-line note in a closed ticket, a recent policy change not reflected in docs, or a “do not contact” flag living in a separate system. Tool outputs can also be misleading: stale caches, ambiguous record matches, silent failures, and permissions that vary by environment. Filling these gaps costs real time—instrumentation, data lineage, and access reviews—work that doesn’t show up in the demo but dominates the safe deployment.
Control surfaces that quietly disappear as autonomy increases
A familiar warning sign is when the agent is “doing great” but no one can answer basic operational questions anymore: what exactly did it change, why did it choose that path, and who approved it. Early on, control surfaces are obvious—buttons, review queues, PR approvals, payment limits. As autonomy increases, those surfaces get replaced by internal prompts, background tool calls, and multi-step chains that look like one action from the outside. The work still happens, but the checkpoints turn implicit and easy to bypass.
Small design choices accelerate the disappearance: auto-retrying failed calls, letting the agent “fix forward” instead of stopping, or collapsing multiple systems behind a single “execute task” permission. The cost shows up when something goes wrong and you realize your only lever is “turn it off.” Restoring control means paying for structure—fine-grained scopes, explicit state machines, audit logs you can trust, and rollback paths that were tested before the first incident.
Risk is not one thing: money, security, safety, reputation
A useful way to calibrate autonomy is to separate risks that get lumped together. Financial risk is often the easiest to bound: caps on refunds, spend limits, rate limits on purchases, and daily totals make worst-case loss legible. Security and privacy risk is different because a single bad tool call can expose data you can’t “refund” back into secrecy—especially when agents can search across systems, export files, or message externally. Safety risk shows up when automation touches the physical world or critical operations: an incorrect “disable alerts” or “restart service” step can create real-world harm or prolonged outage.
Reputation risk is the multiplier. Customers usually forgive a slow process; they rarely forgive receiving the wrong email, being contacted after opting out, or learning an internal note was surfaced. You can’t buy down all categories equally: the same permission (like “send email”) is low-dollar but high-reputation, so controls need to match the specific failure you can’t easily unwind.
Designing agents with brakes: permissions, limits, and verification
The safest agents are designed less like “workers” and more like systems with brakes: they can suggest, stage, and simulate, but they only commit changes through narrow, auditable paths. Start with permissions that match the smallest useful unit of work. “Read-only CRM plus draft reply” is a different class of access than “issue refund,” and “open a pull request” is not “merge to main.” The practical cost is real: you’ll spend time decomposing tools into fine-grained scopes, maintaining separate credentials per environment, and updating access as workflows change.
Limits make worst cases legible. Put hard caps on money movement, message volume, record updates, and retries, and make the agent surface when it hits a boundary instead of “working around” it. Treat high-reputation actions—external email, customer-facing policy exceptions, data exports—as escalation points even if they’re cheap in dollars. Rate limits and circuit breakers also protect you from feedback loops where one bad assumption triggers a storm of tool calls.
Verification is where autonomy becomes earned. Require the agent to fetch and cite the specific fields it relied on, run preflight checks, and produce a diff or transaction preview that a human (or a separate verifier) can approve. Pair this with immutable audit logs, idempotent operations, and rollback playbooks tested in calm conditions, not written during an incident.
A practical autonomy ladder: choosing the right level of control
A practical way to choose autonomy is to treat it like a ladder you climb only when the rung below is boringly reliable. Start with “advisor” mode: the agent reads, summarizes, and drafts, but cannot change state. Move to “operator with staging”: it can open tickets, create pull requests, and prepare refunds or emails as drafts with explicit diffs, but a human commits. The next rung is “bounded executor”: it can commit within tight scopes (specific repos, customers, or queues) and hard limits (daily totals, rate caps, no external messaging), with audit logs and easy rollback.
Full autonomy is reserved for workflows that are frequent, low-reputation, and reversible—like internal routing or cache refreshes—and even then only with circuit breakers. If you can’t confidently answer “what’s the worst-case blast radius?” in dollars, records, and recipients, the rung is too high.
Conclusion: Build for graceful failure before scaling autonomy
You rarely regret an agent that asks for permission too often; you often regret one that commits quietly and forces you into incident mode. Treat autonomy as a production dependency: if you can’t trace actions end-to-end, bound the blast radius, and roll back quickly, you don’t have autonomy—you have latent outage risk.
The operating principle is simple: earn access through boring reliability. Ship read-only and staged actions first, prove monitoring catches drift, prove circuit breakers stop loops, and rehearse rollback with real data shapes. Those guardrails cost time, and they slow demos, but they turn failure into a contained event instead of a customer-facing story you can’t take back.